Introducing ‘Posting Through the Singularity’
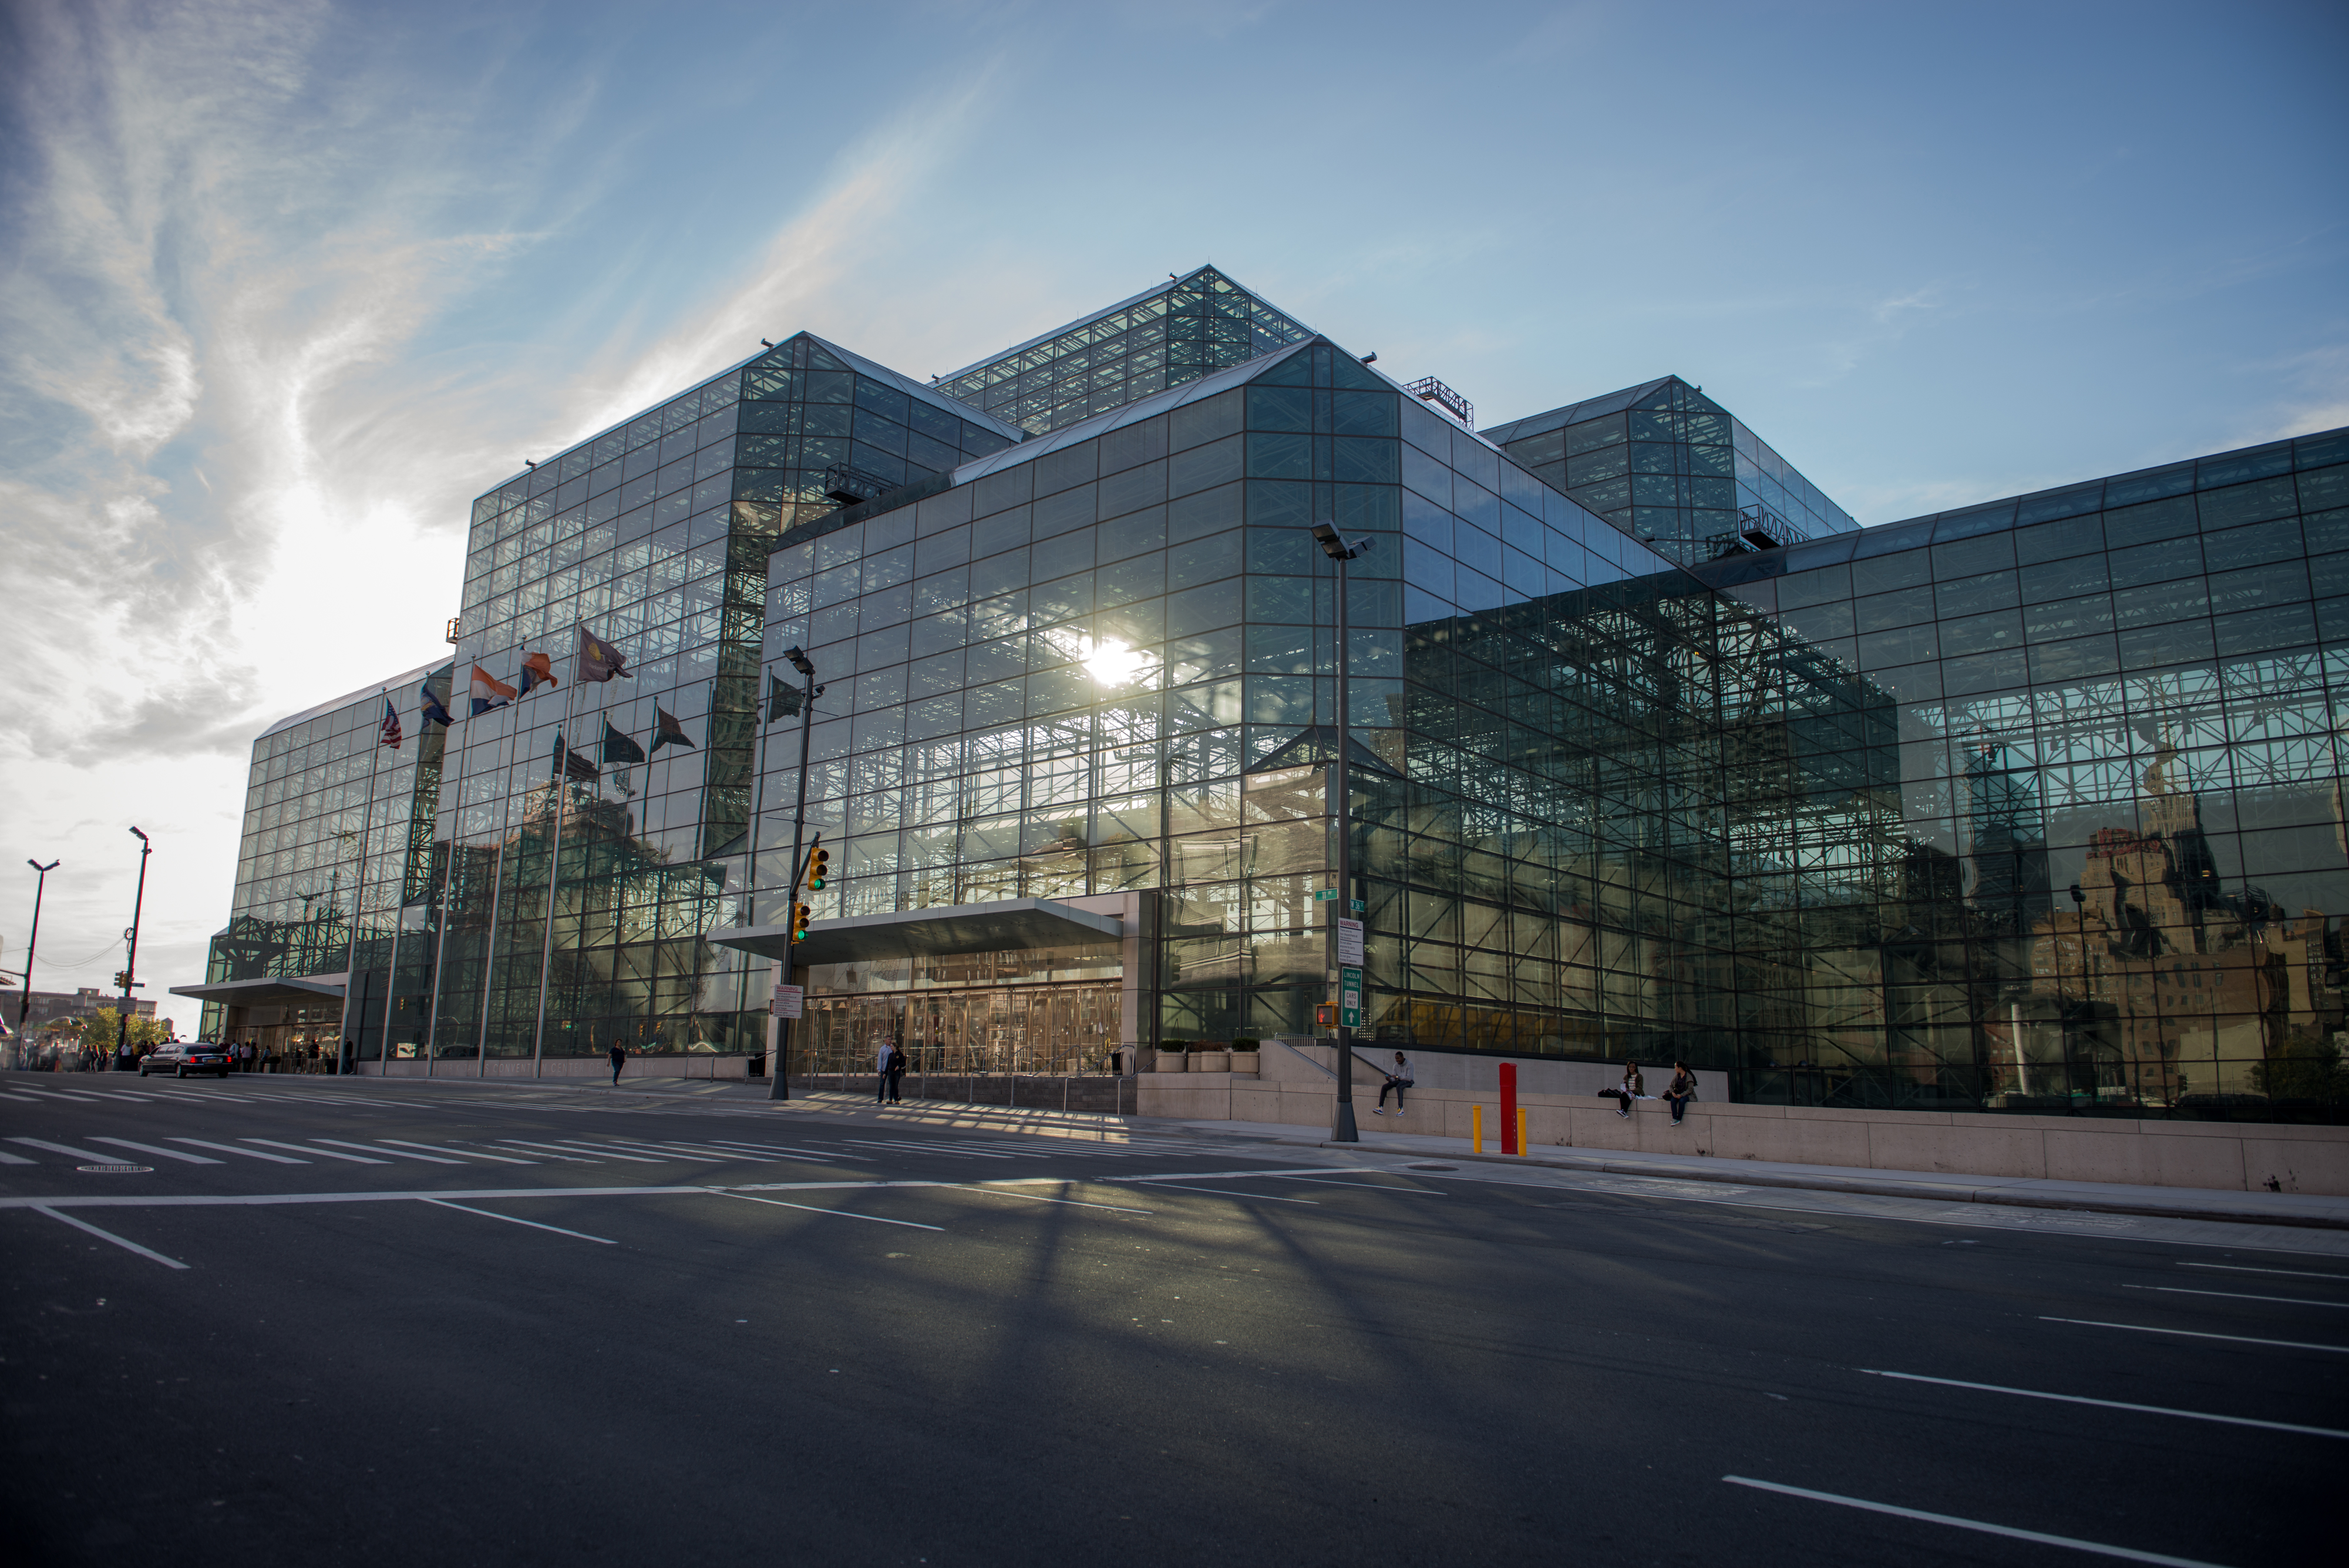
I took the New York bar exam in late July 1990, at the Jacob Javits Center. The exam rooms were cavernous: desk after desk inside the freezing convention halls, row upon row until they receded to a vanishing point. Some 7,400 of us sat that day, and outside news vans lined the parking lot. The media had not come to cover the morning that, decades later, would open my first column on computational jurisprudence. No, they had come because JFK Jr. had flunked the bar twice before, and the whole world wanted to see whether he would flunk it a third time.
I had studied 14 hours a day for six weeks. I had enrolled in a bar-review course, even attended it, taken notes, and sat for practice exams. I took bar prep seriously because I had no choice: I went to Yale Law School. And while I learned many things at Yale, the law was not one of them. I was also starting graduate school in philosophy and did not want to be known around the department as the grad student who, like JFK Jr., failed the bar.
I walked out of the exam reasonably sure I had failed. I am generally good at tests. But out of 200 multiple-choice questions, I was confident I had gotten exactly two right. One was a gift: It asked for the difference between contributory and comparative negligence, which was a matter of a simple definition. (Under contributory negligence, a plaintiff who is even slightly at fault recovers nothing; under comparative negligence, the plaintiff’s recovery is merely reduced in proportion to his share of the fault.) As for the other 198 questions, I was genuinely unsure which was the right answer.
On my way out of the Javits Center, I passed a group of students who had just finished the exam, laughing and high-fiving and discussing how easy it had been. This was not what I needed to hear.
Then one of them said: “I was unsure about only one question. What’s the difference between contributory and comparative negligence?” My mood lifted.
That’s What Logic Is For
I passed, as did JFK Jr. (who later died in a plane crash and, still later, became a main character in the QAnon conspiracy). The bar exam nonetheless remained the hardest exam I had ever taken.
So when OpenAI announced in 2023 that GPT-4 had succeeded in passing the bar, I was shocked: A language model had passed the test that once reduced me to taking comfort in a stranger’s ignorance of contributory negligence.
My astonishment was reasonable. You spend three years in law school and months in preparation for a grueling test of legal knowledge and analysis, and then a language model shows up and passes it. The obvious conclusion was that something important had changed. Soon AI systems were sitting for the MCAT, the CPA exam, the LSAT, and nearly every other standardized test anyone could locate. With each new model the scores went up, and exam performance became the standard measure of machine intelligence.
The appeal is easy to understand: Everyone knows what an exam score means. If the human gets 72 and the machine gets 91, nobody demands a benchmark methodology section. The machine did better than the person.
The trouble is that passing an exam establishes only that a model produced the right answers. It establishes very little about why it produced them, or whether the reasoning behind its answers can be reproduced on demand. This matters when the subject is a complicated system of rules—like, say, a legal code. A regulation contains definitions, exceptions, thresholds, cross-references, and equations. Imagine that one provision applies only if three conditions are satisfied, another overrides it, and a third creates an exception to the override. A language model must keep all of this straight while generating its answer one token at a time.
At the Legal AI Lab at Yale Law School, which I co-direct with Ruzica Piskac, we wanted to know how serious this problem of underlying model reasoning in the legal space remains in frontier models. So we went looking for a professional exam that would force a model to do something harder than recognize patterns, retrieve information, and produce plausible prose answers.
Let me introduce you to the Casualty Actuarial Society’s (CAS’s) Exam 6U. Exam 6U, as it is called, is the regulation exam for casualty actuaries. It is one of the most feared exams in insurance. It served nicely.
Exam 6U is formidable. Most candidates have already passed four or five actuarial exams before taking it, and they spend 300-400 hours preparing for this one, absorbing an extraordinary volume of regulatory detail: RBC action levels, IRIS ratios, Schedule F penalties, and much else. The exam is written-answer only, so there are no multiple-choice options to eliminate. The average pass rate since 2011 is 42 percent. We used the fall 2019 sitting, the last for which the CAS published a full examiner’s report; candidates needed 49.75 of 69.25 points to pass, and the 95th percentile scored 59.63. This is not an exam that rewards vibes.
We gave it to GPT-5.5 three times. It did reasonably well on the open-ended questions. But on the computational questions, it struggled, with a median score of 10 out of 17.5 points, or 57 percent. The failures had a consistent character: The model rarely lacked knowledge of the relevant rule. But it applied the rule incorrectly, or not at all. In short, it knew what the rule was, but not how to use it.
The exam’s Question 15 is a good illustration. Insurers buy insurance of their own, called reinsurance, and they book what their reinsurers owe them as an asset: “recoverables.” Statutory accounting requires a penalty against these IOUs, computed on Schedule F of the annual statement. The size of the penalty depends on a test you must run first—the “slow-paying test”—which asks how much of the debt is overdue and thereby determines which formula applies. For a slow payer, the penalty is one-fifth of the balance not secured by collateral. Got that?
Neither did GPT-5.5. And the reason is interesting: It never ran the slow-paying test. While it could recite the rule, it didn’t understand the rule. Rather, it took a fifth of only the overdue balance, net of collateral, and reported $425,000 as the penalty; the official answer, a fifth of the full $4,095,000 unsecured balance, was $819,000. The model took a rule that says “take a fifth of everything unsecured” and executed it as “take a fifth of whatever is overdue.” The relevant material was in front of it, but that turned out not to be enough.

The difference between knowing the rule and understanding the rule is the subject of my new column for Lawfare.
In it, I will be exploring questions of what happens where artificial intelligence (AI) and law meet. My particular preoccupation will be “computational jurisprudence,” which, as we will see, is even sexier than it sounds.
By computational jurisprudence, I mean treating law as an object of computation. For example, you can study law as a system of instructions and definitions, almost as if it were a computer program: translate statutes and contracts into formal representations, check them for contradictions, or use theorem provers to determine what follows from them. You can use computation to predict how judges, firms, or other legal actors will behave. Or you can use retrieval-augmented generation (RAG), as Lawfare’s editor in chief, Benjamin Wittes, has been doing with RAGtime, Lawfare’s new research platform. RAGtime leverages the power of semantic embeddings to make millions of otherwise unmanageable legal and governmental documents searchable and analyzable.
The analogy here is computational mathematics. Computers have been doing mathematics for a long time. But increasingly, they are being used to construct and verify proofs so complicated that no human being can realistically follow every step. AI is pushing that development much further. This has generated considerable excitement and consternation among mathematicians because it raises an awkward question: What does it mean to understand a proof if a machine can produce or verify it but no person can fully grasp it?
Law is heading toward its own version of that problem. What does it mean to understand the law if a machine can reason across more of it than any lawyer could possibly hold in mind? What counts as legal reasoning, legal knowledge, or even legal expertise under those conditions?
These questions become more urgent in a world in which existential risk from AI no longer seems entirely far-fetched. If increasingly autonomous systems are going to act in the world, law cannot merely be something they are trained to talk about. It has to be something they need to follow—and are programmed to follow in fashions that are not optional or waivable if, say, a group of AI agents decides to hack a company. We will need ways of specifying constraints on what they may do and, in some cases, requiring guarantees that specified actions are impossible for a system to perform. That brings formal logic, verification, and machine-executable rules into the discussion not merely as tools for automating law, but as possible tools for controlling AI itself.
But in this column, I will be ranging considerably further afield: from the nature of legal interpretation to whether large language models will make good lawyers; from using theorem provers to exploit the tax code to applying machine learning to forecast how Supreme Court Justices will decide; from the origins of the field in the pioneering 17th-century work of the philosopher, mathematician, and lawyer Gottfried Leibniz to the coming neuro-symbolic revolution.
There will also be recipes.
My own research, as the Exam 6U example illustrates, lies at the formal end of this spectrum: translating legal rules into machine-executable logic so that applying the law becomes something a computer can calculate and a human can audit. The ambition is not to build a machine that sounds like a lawyer. It is to build one that can ingest a body of rules, determine what the law requires in a particular situation, govern its own conduct accordingly, and show its work along the way. Not guesses you have to trust, but proofs you can verify.
So let me tell you a little about how we got the AI to pass Exam 6U with an even better score than I got on the bar exam.
Reasoning, Not Predicting
Language models are very good at reading rules: They can find them, summarize them, explain them, and often apply them correctly. The word “often” here is (as Claude would say) “load-bearing.” If a regulation says that C follows when A and B are true unless D applies, there is no reason to ask a machine to predict whether C sounds like the right answer. The regulation has already specified the inference: check A, check B, check D, derive C. After all, that’s what logic is for.
So we tried something different with Exam 6U. Using our system, which we call “Leibniz” in homage to the philosopher-lawyer who dreamed of automating legal reasoning, we converted the relevant NAIC regulations and accounting requirements into formal logic—each rule a machine-executable statement, each equation a function—and supplied the facts from the exam questions to a theorem prover, in our case Z3, to determine what followed. The result was 100 percent correct, and not on one lucky run. The same rules and the same facts produced the same answers, every time.
 Notes: The computational portion. GPT-5.5’s figure is the median of three attempts. The Leibniz figure did not require a median.
The point is not that we found a better way to prompt a language model. The point, rather, is that we changed the kind of computation being performed. A language model predicts, and predictions aren’t good enough for legal compliance. A theorem prover, by contrast, deduces. And, once the regulations have been compiled into logic, there is no temperature setting, no prompt engineering, and no fortunate sampling. Either the conclusion follows from the rules or it does not.
This approach has enormous practical consequences. Law, insurance, tax, contracts, and corporate compliance are all built from rules of exactly the kind we worked with here. Definitions establish categories, conditions trigger duties, exceptions defeat rules, thresholds determine consequences, and formulas produce numbers. Language models read these materials very well. It does not follow, however, that they execute them well. The better arrangement is a division of labor: Let the model do what it does remarkably well—reading language, identifying provisions, translating them into structured representations—and then let deterministic systems do what they do well, which is applying rules and proving what follows from them.
The distinction grows more important once we move beyond exams. An AI system that misses a bar-exam question loses a point—which even JFK Jr. could afford. An AI system that approves an insurance claim, calculates a reserve, determines a tax liability, or decides whether a company is complying with the law operates in a domain where “usually right” is a considerably less attractive standard. We need to know which rules produced the answer, and whether they were faithfully applied—or applied at all.
The performance of language models on professional exams encouraged an understandable hope: Make the models large enough, and eventually they will reason through everything. Exam 6U suggests another possibility. Sometimes the answer is not a better model. Sometimes it is to stop predicting and start calculating instead.
In 1990, the bar results came by mail. You waited for an envelope from the New York State Board of Law Examiners and, when it arrived, tore it open to learn whether you had passed. At least the news was private. For years, the more immediate way to find out had been to look for your name on the list of successful candidates published in the New York Law Journal, which, to friends and family, was a very public way to fail the bar. (In 1982, Emily Kennedy was on the list. Her husband at the time, Robert F. Kennedy Jr., who had taken the exam with her, was not.)
Technology has moved on. Today your bar results arrive via email with a link to a secure portal. Soon, an AI agent will notify you on your glasses, having first measured your heartbeat and cortisol levels to make sure you’re ready for the news.
This column will arrive periodically, without notice, and without checking your cortisol. You will know it has dropped when you suddenly find yourself dying to know what the longest sentence in the U.S. Code is,* how Justice Samuel Alito will rule in an upcoming case,** or why, under U.S. tax law, someone can claim themselves as their own dependent provided they do not earn enough to support themselves.***
* Future column, sorry.
** OK, that’s an easy one.
*** Anyone that can prove this gets honorable mention in my next column, and possibly a free copy of Fancy Bear Goes Phishing. Hint: Title 26 § 152(a)(1)–(2); § 152(b)(1); § 152(c)(3)(A); § 152(d)(1)(A); § 152(d)(1)(B); § 152(d)(1)(C); § 152(d)(1)(D); § 152(d)(2)(H). A signed copy for anyone who can show the negation as well.